<< Prev Question Next Question >>
Question 20/33
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
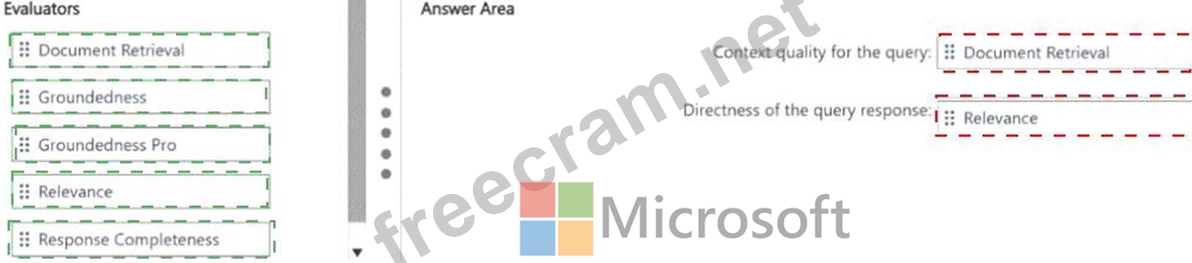
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
You have a dataset that contains query, context, and response without document relevance labels.
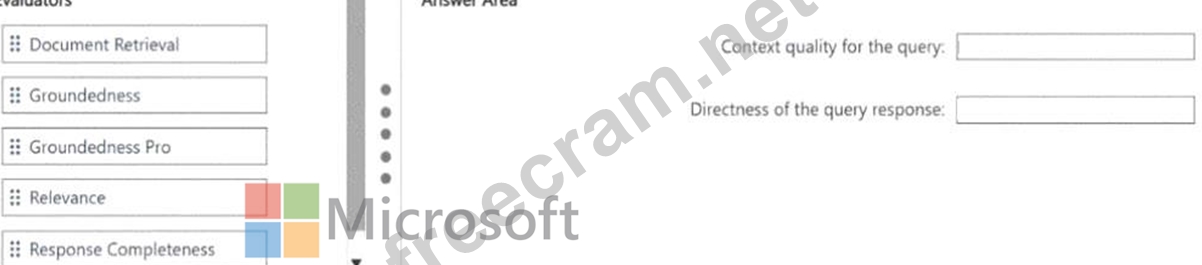
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.