- Home
- Microsoft
- Designing and Implementing a Microsoft Azure AI Solution
- Microsoft.AI-102.v2026-09-19.q184
- Question 165
Valid AI-102 Dumps shared by ExamDiscuss.com for Helping Passing AI-102 Exam! ExamDiscuss.com now offer the newest AI-102 exam dumps, the ExamDiscuss.com AI-102 exam questions have been updated and answers have been corrected get the newest ExamDiscuss.com AI-102 dumps with Test Engine here:
Access AI-102 Dumps Premium Version
(425 Q&As Dumps, 35%OFF Special Discount Code: freecram)
<< Prev Question Next Question >>
Question 165/184
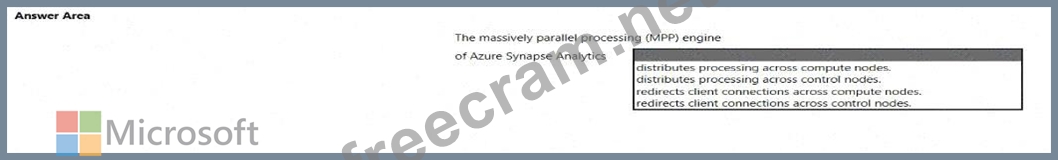
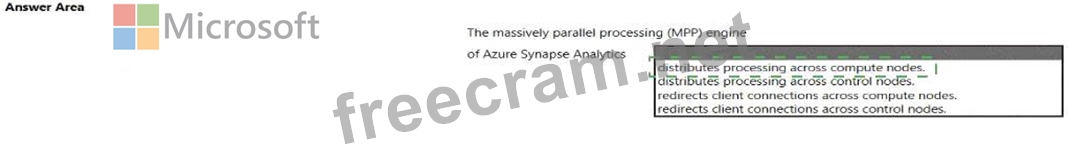
Select the answer that correctly completes the sentence.
Correct Answer:
Explanation:
Azure Synapse Analytics (formerly Azure SQL Data Warehouse) uses a massively parallel processing (MPP) architecture for big data and analytics workloads.
Control Node:
Acts as the brain of the system.
Receives queries, optimizes them, and then coordinates execution.
Does not perform large-scale data crunching itself.
Compute Nodes:
Perform the actual parallel execution of queries.
Data is distributed across these nodes.
The MPP engine breaks down queries into smaller tasks and distributes them to compute nodes for fast, parallel execution.
Review of Answer Options:
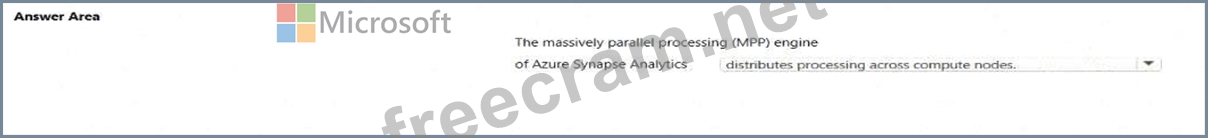
Distributes processing across compute nodes # Correct. This is the essence of MPP.
Distributes processing across control nodes # Incorrect. The control node does not process queries in parallel; it coordinates them.
Redirects client connections across compute nodes # Incorrect. Client connections go to the control node, not directly to compute nodes.
Redirects client connections across control nodes # Incorrect. There is typically one control node per Synapse instance.
The answer: Distributes processing across compute nodes
Microsoft References
Azure Synapse Analytics architecture
Distributed query processing in Azure Synapse


- Question List (184q)
- Question 1: You have an Azure subscription that contains an Azure OpenAl...
- Question 2: You have a video recording of a company meeting that include...
- Question 3: You are developing an application that will use the Computer...
- Question 4: You have an Azure subscription that contain an Azure OpenAI ...
- Question 5: You plan to perform predictive maintenance. You collect IoT ...
- Question 6: You need to analyze video content to identify any mentions o...
- Question 7: You have a Custom Vision resource named acvdev in a developm...
- Question 8: You have an Azure subscription that contains an Azure Al Doc...
- Question 9: You build a QnA Maker resource to meet the chatbot requireme...
- Question 10: You manage an application that stores data in a shared folde...
- Question 11: You have an app named App1 that uses Azure Al Document Intel...
- Question 12: You have a Language Understanding resource named lu1. You bu...
- Question 13: For each of the following statements, select Yes if the stat...
- Question 14: You plan to build an app that will generate a list of tags f...
- Question 15: You plan create an index for an Azure Cognitive Search servi...
- Question 16: You have a Microsoft Foundry project named Project1. You pla...
- Question 17: You have the following data sources: * Finance: On-premises ...
- Question 18: What should you use to automatically delete blobs from Azure...
- Question 19: You have receipts that are accessible from a URL. You need t...
- Question 20: You have an Azure subscription that contains an Azure Al Lan...
- Question 21: You train a Conversational Language Understanding model to u...
- Question 22: You are developing an app that will use the Speech and Langu...
- Question 23: You have an Azure Al Speech service resource named Resource1...
- Question 24: Match the Azure services to the appropriate locations in the...
- Question 25: You need to develop an extract solution for the receipt imag...
- Question 26: You build a conversational bot named bot1. You need to confi...
- Question 27: You are building an agent by using the Azure Al Foundry Agen...
- Question 28: You are designing two Azure Al agents named Agent 1 and Agen...
- Question 29: You have a SQL query that combines customer data and order d...
- Question 30: You have a product knowledgebase that contains multiple PDF ...
- Question 31: You are building a Language Understanding solution. You disc...
- Question 32: You have an Azure subscription. You plan to build an app tha...
- Question 33: You have an Azure Cognitive Search solution and a collection...
- Question 34: You have a bot that was built by using the Microsoft Bot Fra...
- Question 35: You have an Azure subscription that contains a Microsoft Fou...
- Question 36: Select the answer that correctly completes the sentence. (Ex...
- Question 37: Note: This question is part of a series of questions that pr...
- Question 38: You are developing a solution to generate a word cloud based...
- Question 39: You have a file share that contains 5,000 images of scanned ...
- Question 40: Note: This question is part of a series of questions that pr...
- Question 41: You have an Azure subscription that contains an Azure OpenAI...
- Question 42: You are developing a text processing solution. You have the ...
- Question 43: Note: This question is part of a series of questions that pr...
- Question 44: You are designing a conversational interface for an app that...
- Question 45: You have an app that uses an Azure Al Foundry Content Safety...
- Question 46: You have a chatbot that was built by using Microsoft Bot Fra...
- Question 47: You are building a flight booking bot by using the Microsoft...
- Question 48: You build a custom Form Recognizer model. You receive sample...
- Question 49: You are building an app that will perform speech translation...
- Question 50: You have an Azure subscription that contains an Azure Al Con...
- Question 51: You have an Azure subscription that contains an Azure OpenAI...
- Question 52: You have an Azure subscription that has the following config...
- Question 53: You are reviewing the design of a chatbot. The chatbot inclu...
- Question 54: You are building a social media messaging app. You need to i...
- Question 55: You are developing a method for an application that uses the...
- Question 56: You have a product knowledgebase that contains multiple PDF ...
- Question 57: You are building a message handling system that will use the...
- Question 58: You have an Azure subscription. You need to deploy an Azure ...
- Question 59: You build a bot by using the Microsoft Bot Framework SDK. Yo...
- Question 60: You are building a Conversational Language Understanding mod...
- Question 61: You are building a Language Understanding model for an e-com...
- Question 62: You deploy a web app that is used as a management portal for...
- Question 63: What is the primary purpose of a data warehouse?...
- Question 64: You are building a chatbot by using the Microsoft Bot Framew...
- Question 65: You are building a solution in Azure that will use Azure AI ...
- Question 66: You have an Azure Al agent solution. You plan to create an a...
- Question 67: What is used to define a query in a stream processing jobs i...
- Question 68: You are building a language learning solution. You need to r...
- Question 69: You develop a Conversational Language Undemanding model by u...
- Question 70: You are building a chatbot. You need to use the Content Mode...
- Question 71: Note: This question is part of a series of questions that pr...
- Question 72: You are building an app that will share user images. You nee...
- Question 73: You plan to use a Language Understanding application named a...
- Question 74: You have a Video Indexer service that is used to provide a s...
- Question 75: You use the Microsoft Bot Framework Composer to build a chat...
- Question 76: Note: This question is part of a series of questions that pr...
- Question 77: You have an Azure subscription that contains a Content Safet...
- Question 78: Select the answer that correctly completes the sentence. (Ex...
- Question 79: What is a characteristic of a non-relational database?...
- Question 80: You are developing a photo application that will find photos...
- Question 81: You develop a test method to verify the results retrieved fr...
- Question 82: You have an app that uses a Content Safety in Foundry Contro...
- Question 83: You have an app named App1 that uses a custom Azure Al Docum...
- Question 84: Note: This question is part of a series of questions that pr...
- Question 85: You have a question answering project in Azure Cognitive Ser...
- Question 86: You are developing a solution for the Management-Bookkeepers...
- Question 87: You have an Azure Cognitive Search solution and a collection...
- Question 88: You are building a chatbot. You need to configure the bot to...
- Question 89: You are developing the document processing workflow. You nee...
- Question 90: You are building a call handling system that will perform th...
- Question 91: You are developing a webpage that will use the Video Indexer...
- Question 92: Note: This question is part of a series of questions that pr...
- Question 93: You Build a bot in JavaScript. From the Azure Command-Line i...
- Question 94: Select the answer that correctly completes the sentence. (Ex...
- Question 95: You are developing the knowledgebase. You use Azure Video An...
- Question 96: You are building a model to detect objects in images. The pe...
- Question 97: You need to build a chatbot that meets the following require...
- Question 98: You have an Azure subscription that contains a multi-service...
- Question 99: You have an Azure subscription that contains an Azure Al ser...
- Question 100: You are building an app that will automatically translate sp...
- Question 101: You train a Custom Vision model used in a mobile app. You re...
- Question 102: You have a text-based chatbot. You need to enable content mo...
- Question 103: You are developing the knowledgebase by using Azure Cognitiv...
- Question 104: You have 100,000 documents. You are building an app that wil...
- Question 105: You are building a Language Understanding model for purchasi...
- Question 106: You are building an Azure web app named App1 that will trans...
- Question 107: You are building an agent by using custom question answering...
- Question 108: You have an Azure subscription that contains an Azure Al Con...
- Question 109: You have an Azure subscription. You plan to build an app tha...
- Question 110: You are building an app that will translate speech by using ...
- Question 111: Note: This question is part of a series of questions that pr...
- Question 112: Note: This question is part of a series of questions that pr...
- Question 113: You have an existing Azure Cognitive Search service. You hav...
- Question 114: You have an Azure subscription that contains an Azure Al Lan...
- Question 115: You have 100,000 images. You need to build an app that will ...
- Question 116: You are building a call handling system that will receive ca...
- Question 117: You have an Azure subscription. You are building a social me...
- Question 118: Match the types of workloads to the appropriate scenarios. T...
- Question 119: You are developing a system that will monitor temperature da...
- Question 120: You have an Azure subscription that contains an Azure Al Lan...
- Question 121: You are building an agent by using the Microsoft Foundry Age...
- Question 122: You have a chatbot that was built by using the Microsoft Bot...
- Question 123: You plan to deploy a containerized version of an Azure Cogni...
- Question 124: You have a custom model named ModeM in the Azure Translator ...
- Question 125: You have an Azure subscription that contains an Azure App Se...
- Question 126: You ace developing an app that will use the Speech and langu...
- Question 127: You are designing an Azure AI solution to identify defective...
- Question 128: You have an Azure subscription. You need to deploy an Azure ...
- Question 129: You develop an app in O named App1 that performs speech-to-s...
- Question 130: You need to build an app that will use the Azure Al Speech s...
- Question 131: You have an app named App1 that uses an Azure Cognitive Serv...
- Question 132: You are building an agent that will retrieve the current tim...
- Question 133: You are developing a new sales system that will process the ...
- Question 134: You have an Azure subscription that contains an Azure OpenAI...
- Question 135: You plan to build an agent that will combine and process mul...
- Question 136: You have an Azure subscription. You are building a chatbot t...
- Question 137: You have a chatbot. You need to test the bot by using the Bo...
- Question 138: You are building a bot on a local computer by using the Micr...
- Question 139: You are building a solution that will detect anomalies in se...
- Question 140: You plan to deploy an Azure OpenAI resource by using an Azur...
- Question 141: You have a Custom Vision service project that performs objec...
- Question 142: You have the following files: * File1.pdf * File2.jpg * File...
- Question 143: You are building an app that will provide users with definit...
- Question 144: Note: This question is part of a series of questions that pr...
- Question 145: Your company uses an Azure Cognitive Services solution to de...
- Question 146: You are building an app that will analyze documents by using...
- Question 147: You have an Azure Cognitive Search solution and an enrichmen...
- Question 148: You are developing an app that will use the Azure AI vision ...
- Question 149: You develop a custom question answering project in Azure Cog...
- Question 150: Select the answer that correctly completes the sentence. (Ex...
- Question 151: You have a Microsoft OneDrive folder that contains a 20-GB v...
- Question 152: You are building an app that uses a Language Understanding m...
- Question 153: You plan to provision a QnA Maker service in a new resource ...
- Question 154: Note: This question is part of a series of questions that pr...
- Question 155: You plan to provision Azure AI service resources by using th...
- Question 156: A customer uses Azure Cognitive Search. The customer plans t...
- Question 157: Match the Azure Cosmos DB APIs to the appropriate data struc...
- Question 158: You plan to build an agent that will combine and process mul...
- Question 159: Which database transaction property ensures that transaction...
- Question 160: You are developing a method that uses the Computer Vision cl...
- Question 161: You have an Azure subscription that contains an Azure OpenA1...
- Question 162: You are building a retail chatbot that will use a QnA Maker ...
- Question 163: You need to store event log data that is semi-structured and...
- Question 164: You are developing the shopping on-the-go project. You are c...
- Question 165: Select the answer that correctly completes the sentence. (Ex...
- Question 166: You are building an app by using the Speech SDK. The app wil...
- Question 167: You are building an Al solution that will use Sentiment Anal...
- Question 168: You have an Azure Subscription that contains an Azure OpenAI...
- Question 169: You are building an app that will use Azure Al Language to e...
- Question 170: What ate two uses of data visualization? Each correct answer...
- Question 171: You have an app that analyzes images by using the Computer V...
- Question 172: You have an Azure OpenAI model named All. You are building a...
- Question 173: You are building a phone call handling solution that will us...
- Question 174: You have an Azure subscription that contains an Azure OpenA1...
- Question 175: You have a mobile app that manages printed forms. You need t...
- Question 176: You have an Azure Cognitive Search resource named Search 1 t...
- Question 177: You are building an agent by using the Semantic Kernel. The ...
- Question 178: You have an Azure subscription that contains an Azure Al Con...
- Question 179: Select the answer that correctly completes the sentence. (Ex...
- Question 180: You are designing a conversation flow to be used in a chatbo...
- Question 181: You are building an agent by using the Azure Al Agent Servic...
- Question 182: You have a custom analyzer named analyzer1 that performs the...
- Question 183: You are building a chatbot. You need to use the Content Mode...
- Question 184: You have the following data sources: Finance: On-premises Mi...

