Valid AB-731 Dumps shared by ExamDiscuss.com for Helping Passing AB-731 Exam! ExamDiscuss.com now offer the newest AB-731 exam dumps, the ExamDiscuss.com AB-731 exam questions have been updated and answers have been corrected get the newest ExamDiscuss.com AB-731 dumps with Test Engine here:
Access AB-731 Dumps Premium Version
(98 Q&As Dumps, 35%OFF Special Discount Code: freecram)
<< Prev Question Next Question >>
Question 19/42
- Select the answer that correctly completes the sentence.
An organization that runs continuous, large-scale workloads with Azure OpenAI models should choose the
__________ pricing model.
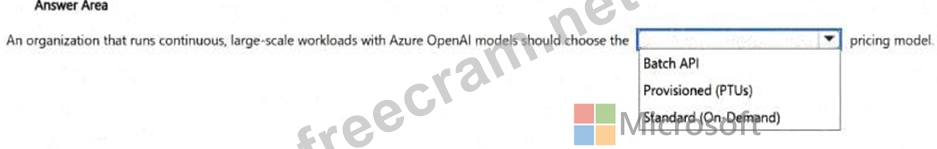
An organization that runs continuous, large-scale workloads with Azure OpenAI models should choose the
__________ pricing model.
Correct Answer:
Explanation:
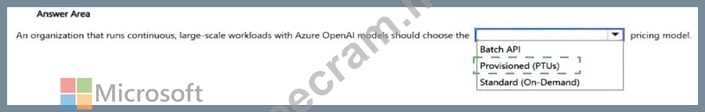
Provisioned (PTUs)
For continuous, large-scale workloads, the key needs are predictable throughput, consistent latency, and cost
/performance stability. Azure OpenAI Provisioned Throughput Units (PTUs) are designed for this scenario because you reserve model capacity to meet sustained demand. This reduces the risk of variability that can occur with purely on-demand usage during peak periods and provides a more predictable operating model when the workload is always "on" and high volume.
Standard (On-Demand) is best when usage is variable or you're starting small (PoCs, pilots, spiky workloads), because it is flexible pay-as-you-go but can be less predictable at sustained scale. Batch API is optimized for asynchronous, non-interactive processing where you can tolerate delayed results (for example, large offline summarization jobs), not for always-on, real-time interactions at scale.
Therefore, for continuous high-volume production workloads, Provisioned (PTUs) is the best pricing model choice.


- Question List (42q)
- Question 1: - Select the answer that correctly completes the sentence. T...
- Question 2: In which scenario is Azure Machine Learning most likely to d...
- Question 3: For each of the following statements, select Yes if the stat...
- Question 4: Your company plans to use generative AI to help summarize an...
- Question 5: Your company is developing an AI-powered customer support ag...
- Question 6: HOTSPOT - For each of the following statements, select Yes i...
- Question 7: Your company sells hiking and camping gear online. You need ...
- Question 8: For each of the following statements, select Yes if the stat...
- Question 9: Match the business scenario to the appropriate AI solution d...
- Question 10: For each of the following statements, select Yes if the stat...
- Question 11: - Select the answer that correctly completes the sentence. U...
- Question 12: Your company manages a website that publishes daily news art...
- Question 13: You need to recommend an AI solution for each task. The solu...
- Question 14: Your company stores hundreds of internal business reports. Y...
- Question 15: For each of the following statements, select Yes if the stat...
- Question 16: - For each of the following statements, select Yes if the st...
- Question 17: For each of the following statements, select Yes if the stat...
- Question 18: For each of the following statements, select Yes if the stat...
- Question 19: - Select the answer that correctly completes the sentence. A...
- Question 20: Your company has a Microsoft 365 subscription and uses Micro...
- Question 21: Your company is reviewing a new AI solution before deploying...
- Question 22: - What should you use for each task? To answer, select the a...
- Question 23: Select the answer that correctly completes the sentence. (Ex...
- Question 24: Select the answer that correctly completes the sentence. The...
- Question 25: Your company purchases Microsoft 365 Copilot for its sales d...
- Question 26: For each of the following statements, select Yes if the stat...
- Question 27: Your company deploys an AI-powered loan approval solution th...
- Question 28: Your company has an AI solution that uses a prebuilt Azure O...
- Question 29: You need to create an AI assistant for a public customer sup...
- Question 30: Which business requirement most closely relates to grounding...
- Question 31: Your company stores thousands of reports and documents acros...
- Question 32: Select the answer that correctly completes the sentence. Pro...
- Question 33: You are exploring how Microsoft 365 Copilot uses Microsoft G...
- Question 34: For each of the following statements, select Yes if the sta...
- Question 35: You have a historical dataset that contains 1,000 records. Y...
- Question 36: For each of the following statements, select Yes if the stat...
- Question 37: - For each of the following statements, select Yes if the st...
- Question 38: Your company discovers that several employees use personal C...
- Question 39: Your company plans to use generative AI to help build a webs...
- Question 40: DRAG DROP - Match the Microsoft responsible AI principles to...
- Question 41: Select the answer that correctly completes the sentence. (Ex...
- Question 42: Select the answer that correctly completes the sentence. (Ex...
